# homogenize fields between python and spreadsheet
**URL:** https://discourse.paraview.org/t/homogenize-fields-between-python-and-spreadsheet/17580
**Category:** Feature Requests
**Tags:** python
**Created:** [May 22, 2026, 1:39pm UTC](https://discourse.paraview.org/t/homogenize-fields-between-python-and-spreadsheet/17580 "2026-05-22T13:39:54Z")
**Posts on this page:** 4
**Page:** 1
### Author:  [@otaolafr](https://discourse.paraview.org/u/otaolafr)
#### Post date: [May 22, 2026, 1:39pm UTC](https://discourse.paraview.org/t/homogenize-fields-between-python-and-spreadsheet/17580/1 "2026-05-22T13:39:54Z")
Hello,
i would like to ask for the homogenization of what we ‘see’ on the spreadsheet and what we ‘use’ in python (regarding the names of fields). one example of this is ‘Point Id’, i wanted to use it:
```auto
QuerySelect(QueryString=f'(in1d("Point ID", {list(IDsNodesToRemove)}))', FieldType="POINT", InsideOut=False)
```
or
```auto
QuerySelect(QueryString=f'(in1d("Point\ ID", {list(IDsNodesToRemove)}))', FieldType="POINT", InsideOut=False)
```
but instead it one should use “id”
same thing when trying to extract specific data in python using fetch, if one wants to get any field of the spreadsheet one would use:
```auto
fieldData=data.PointData[field]
```
but for specific filters this can be called differently such as points/pointsLocations which in _ **practice** _ are the same (coordinates of the points on the filter), but to get them in fetch we need to use completly different things:
```auto
fieldData=data.PointData['PointLocations']
```
or
```auto
fiedlData=data.Points[:]
```
I understand that in the ‘back’ are not the same, but for the user they are. would be nice that this small discrepancies would be homogenized, to smooth out the GUI to python transitions sometimes.
---
### Author:  [@mwestphal](https://discourse.paraview.org/u/mwestphal)
#### Post date: [June 9, 2026, 1:58pm UTC](https://discourse.paraview.org/t/homogenize-fields-between-python-and-spreadsheet/17580/2 "2026-06-09T13:58:31Z")
Maybe im not following, can you clarify what is NOT working and should be in your opinion ?
---
### Author:  [@otaolafr](https://discourse.paraview.org/u/otaolafr)
#### Post date: [June 9, 2026, 2:22pm UTC](https://discourse.paraview.org/t/homogenize-fields-between-python-and-spreadsheet/17580/3 "2026-06-09T14:22:21Z")
sorry if i was not clear. the issue itself is concerning what we ‘see’ in the spreadsheet view (in regards to the column names) and how to acces this data in python
for example:
1. when you want to select using QuerySelect if you have your filter that in the spreadsheet you see the column Point ID, and you want to select the ids [4,19,99], one would think to use:
```auto
QuerySelect(QueryString=f'(in1d("Point ID", {list(IDsNodesToRemove)}))', FieldType="POINT", InsideOut=False)
```
as the column in the spreadsheet says ‘Point ID’ but no, one needs to use:
```auto
QuerySelect(QueryString=f'(in1d("id", {list(IDsNodesToRemove)}))', FieldType="POINT", InsideOut=False)
```
1. when we want to extract an array of a filter in paraview we need to:
```auto
data=dsa.WrapDataObject(servermanager.Fetch(filter)) #get the data of the filter
fieldData=data.PointData[field] #get the specific array that we are looking for (ie., field)
```
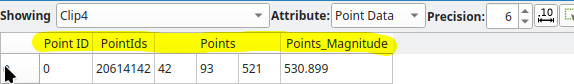
what I was pointing with my original post, is that the line of fieldData will work for every field that is shown in a filter (so each column of the spreadsheet view of the filter), but there are some columns on the spreadsheet that are not accessible using this, (as they are not data arrays) such as Point ID, Points, Points\_Magnitude, among others, that for example, they will be accessible using `fiedlData=data.Points[:]` instead.
Specially as the data.PointData[field] does not give any warning in case of giving a wrong field and return simply a `paraview.vtk.numpy_interface.dataset_adapter.VTKNoneArray` this is sometimes quite annoying (as it is not evident why your script is not working and it is because you have a NoneArray as you tried to recover a column of the spreadsheet with the wrong command and can make crash one’s script easily.
my post was to be able to unify this, ie., be able for example to do:
`fieldData=data.PointData['Points']` and get the corresponding array. basically be able to access everything we see on the spreadsheet by using the name of the specific column in the spreadsheet.
be able to use this names directly:
---
### Author:  [@mwestphal](https://discourse.paraview.org/u/mwestphal)
#### Post date: [June 9, 2026, 2:28pm UTC](https://discourse.paraview.org/t/homogenize-fields-between-python-and-spreadsheet/17580/4 "2026-06-09T14:28:04Z")
Got it, that makes sense.