# How to increase the reading speed of Paraview with large data sets from OpenFoam
**URL:** https://discourse.paraview.org/t/how-to-increase-the-reading-speed-of-paraview-with-large-data-sets-from-openfoam/16024
**Category:** ParaView Support
**Tags:** openfoam, cfd, vtk
**Created:** [January 22, 2025, 4:12pm UTC](https://discourse.paraview.org/t/how-to-increase-the-reading-speed-of-paraview-with-large-data-sets-from-openfoam/16024 "2025-01-22T16:12:47Z")
**Posts on this page:** 11
**Page:** 1
### Author:  [@BrayanGM](https://discourse.paraview.org/u/BrayanGM)
#### Post date: [January 22, 2025, 4:12pm UTC](https://discourse.paraview.org/t/how-to-increase-the-reading-speed-of-paraview-with-large-data-sets-from-openfoam/16024/1 "2025-01-22T16:12:47Z")
Hello,
I am working with LES simulations that generate large data files. I am working on a cluster with OpenFoam and Paraview 5.13.1, running natively on the cluster. Paraview runs in parallel and also uses a GPU. The problem is that it takes a long time to load an Openfoam case, about 20 minutes for each Time Step with a Decompose Case.
So the first question is: In your opinion, what is the most efficient way to load the case: with an OpenFoam Recompose Case, a Decompose Case or converting the files to VTK format?
I think the bottleneck is the HDD’s but seeing the usage, they are not working at their maximum reading capacity, so please give me your opinions on what else it could be.
Thanks for yours response.
---
### Author:  [@mwestphal](https://discourse.paraview.org/u/mwestphal)
#### Post date: [January 23, 2025, 1:16pm UTC](https://discourse.paraview.org/t/how-to-increase-the-reading-speed-of-paraview-with-large-data-sets-from-openfoam/16024/2 "2025-01-23T13:16:12Z")
> [@BrayanGM](#):
>
> In your opinion, what is the most efficient way to load the case: with an OpenFoam Recompose Case, a Decompose Case or converting the files to VTK format?
With a DecomposeCase and a distributed pvserver using multiple nodes and an efficient parallel filesystem.
---
### Author:  [@BrayanGM](https://discourse.paraview.org/u/BrayanGM)
#### Post date: [January 29, 2025, 2:48pm UTC](https://discourse.paraview.org/t/how-to-increase-the-reading-speed-of-paraview-with-large-data-sets-from-openfoam/16024/3 "2025-01-29T14:48:25Z")
Thanks for your reply Mathieu.
I’m working on it, but when I run pvserver or even pvbatch i can’t use the full power of the cluster even in on node.
I use both comands (mpirun or mpiexec), but neither uses all the processors I assigned, in fact I can only assign the number of available GPUs which are 3 per node and still it does not use them, it only uses 3 CPU processors
- mpiexec -np 38 pvbatch Render.py --mesa --parallel
- mpirun -np 38 pvbatch Render.py --mesa --parallel
What else can I do or check to use all the processors of my cluster?
---
### Author:  [@mwestphal](https://discourse.paraview.org/u/mwestphal)
#### Post date: [January 29, 2025, 2:49pm UTC](https://discourse.paraview.org/t/how-to-increase-the-reading-speed-of-paraview-with-large-data-sets-from-openfoam/16024/4 "2025-01-29T14:49:31Z")
> [@BrayanGM](#):
>
> it only uses 3 processors
Is your decomposed OpenFOAM data only split in three part ?
---
### Author:  [@BrayanGM](https://discourse.paraview.org/u/BrayanGM)
#### Post date: [January 29, 2025, 2:58pm UTC](https://discourse.paraview.org/t/how-to-increase-the-reading-speed-of-paraview-with-large-data-sets-from-openfoam/16024/5 "2025-01-29T14:58:36Z")
It is splited in 360 processors
---
### Author:  [@mwestphal](https://discourse.paraview.org/u/mwestphal)
#### Post date: [January 29, 2025, 2:59pm UTC](https://discourse.paraview.org/t/how-to-increase-the-reading-speed-of-paraview-with-large-data-sets-from-openfoam/16024/6 "2025-01-29T14:59:28Z")
> [@BrayanGM](#):
>
> What else can I do or check to use all the processors of my cluster?
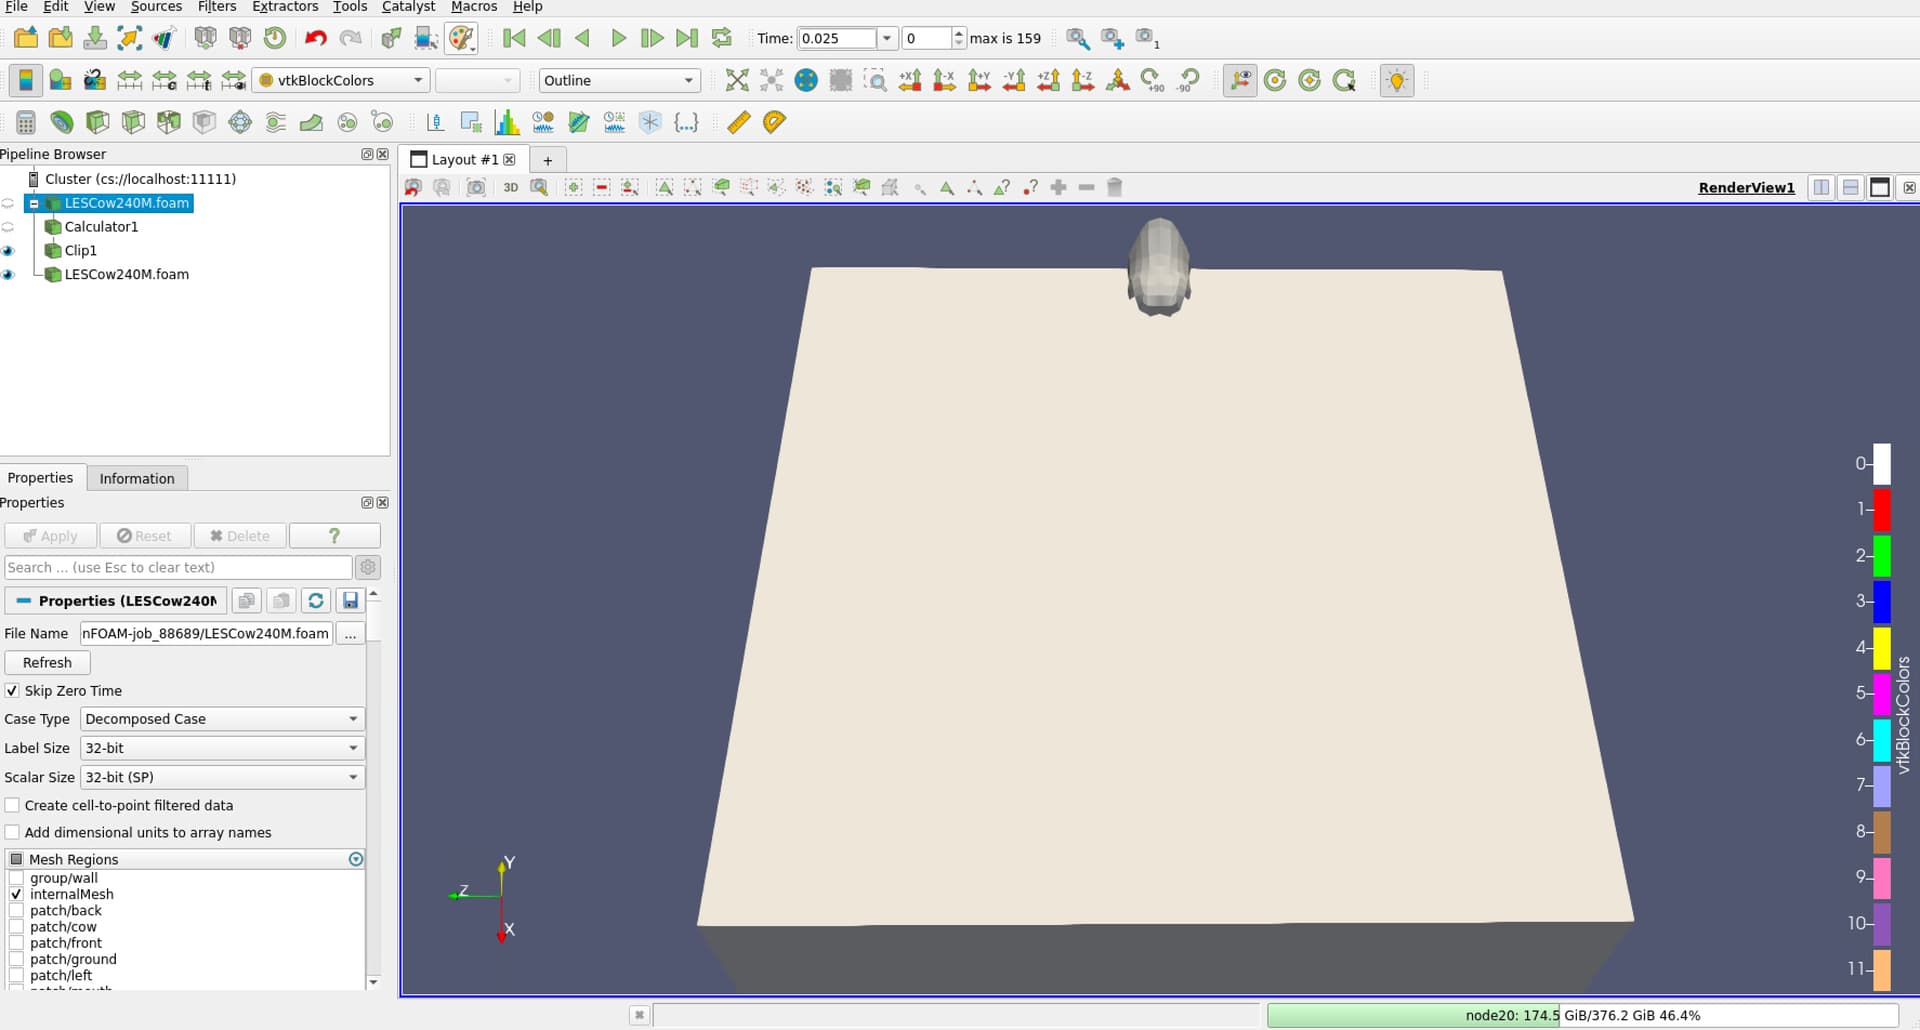
When you visualize it in ParaView with vtkBlockColors, how many blocks do you see ?
---
### Author:  [@BrayanGM](https://discourse.paraview.org/u/BrayanGM)
#### Post date: [January 29, 2025, 7:52pm UTC](https://discourse.paraview.org/t/how-to-increase-the-reading-speed-of-paraview-with-large-data-sets-from-openfoam/16024/7 "2025-01-29T19:52:09Z")
I don’t know how many blocks I see or if it’s only one, I attached a screenshot

---
### Author:  [@otaolafr](https://discourse.paraview.org/u/otaolafr)
#### Post date: [January 29, 2025, 9:32pm UTC](https://discourse.paraview.org/t/how-to-increase-the-reading-speed-of-paraview-with-large-data-sets-from-openfoam/16024/8 "2025-01-29T21:32:02Z")
curious about this as my bottle neck is also paraview and clearly I think i am using it wrong somewhere. my case are decomposed into 8 processors, and in the visualization of the .foam file if i choose vtk coloring i get as brayan, 12 values, but my complete geometry is grey (i clipped in case that they were inside of the mesh but no the mesh is fully grey) i tried to use threshold to see but i could not select vtk block colors for this.
when I am running paraview i am simply calling `$paraviewPath/paraview sim.foam` and when using pvbatch same `$paraviewPath/pvbatch sim.foam` I am using the nightly version of paraview, the simulations were done in OpenFOAM ESI 2406 version (in case it matters).
I imagine that I am doing something wrong. Also when I open the sim.foam the terminal that runs paraview outputs
```auto
VisRTX 0.1.6, using devices:
0: NVIDIA RTX A3000 Laptop GPU (Total: 6.1 GB, Available: 4.3 GB)
```
thanks in advance
---
### Author:  [@wascott](https://discourse.paraview.org/u/wascott)
#### Post date: [January 29, 2025, 9:43pm UTC](https://discourse.paraview.org/t/how-to-increase-the-reading-speed-of-paraview-with-large-data-sets-from-openfoam/16024/9 "2025-01-29T21:43:26Z")
Brayan,
A few fundamental questions. Are you running in Parallel?
- Run Help/ About/ Remote Connection? Does this say you have a remote server?
- View/ Memory Inspector. How many processes/ ranks are you running? The memory inspector will show you memory footprint for each rank.
Lets not talk “processes” as the ParaView reader doesn’t care. How many files are in your dataset?
Franco,
You are running ParaView and pvbatch with a built in server, as opposed to a parallel cluster. Reading in serial is going to be slower than a parallel cluster.
Alan
---
### Author:  [@mwestphal](https://discourse.paraview.org/u/mwestphal)
#### Post date: [January 30, 2025, 8:08am UTC](https://discourse.paraview.org/t/how-to-increase-the-reading-speed-of-paraview-with-large-data-sets-from-openfoam/16024/10 "2025-01-30T08:08:17Z")
Right, this will not provide information.
Could you share your data ? This would make investigation easier.
---
### Author:  [@BrayanGM](https://discourse.paraview.org/u/BrayanGM)
#### Post date: [January 31, 2025, 8:44pm UTC](https://discourse.paraview.org/t/how-to-increase-the-reading-speed-of-paraview-with-large-data-sets-from-openfoam/16024/11 "2025-01-31T20:44:11Z")
Hello Walter and Mathieu, thank you for your help.
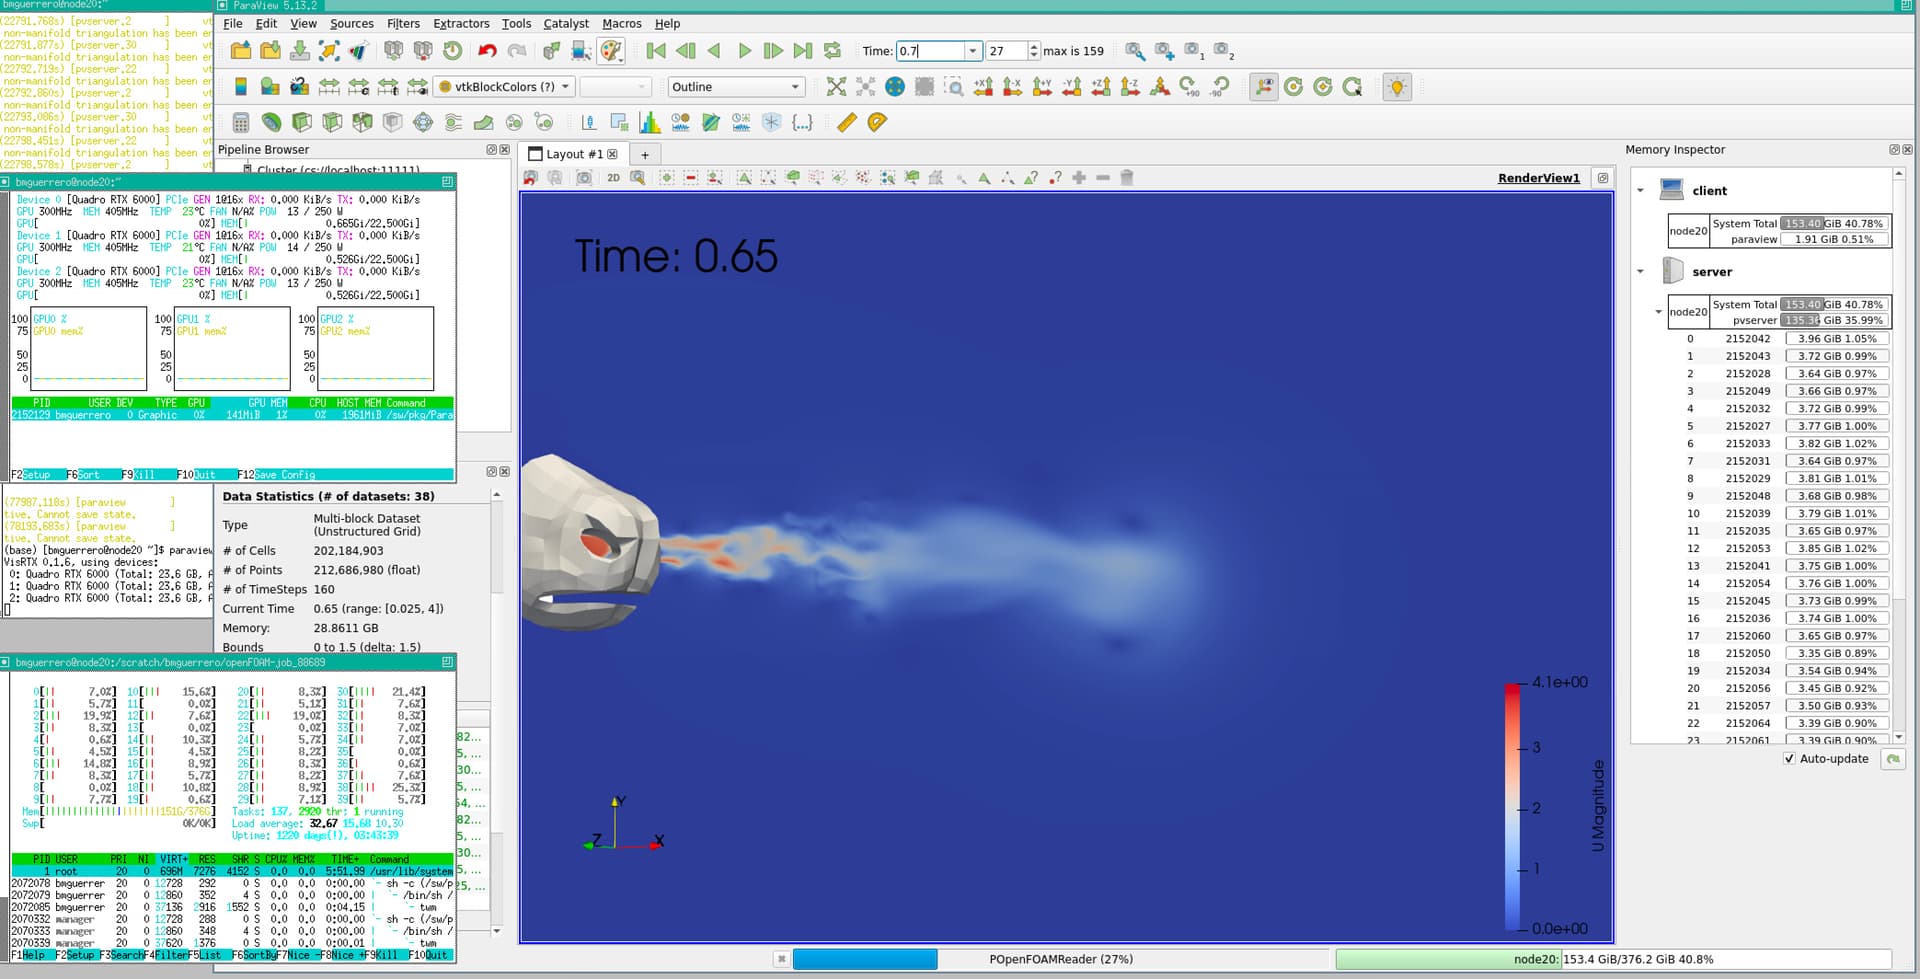
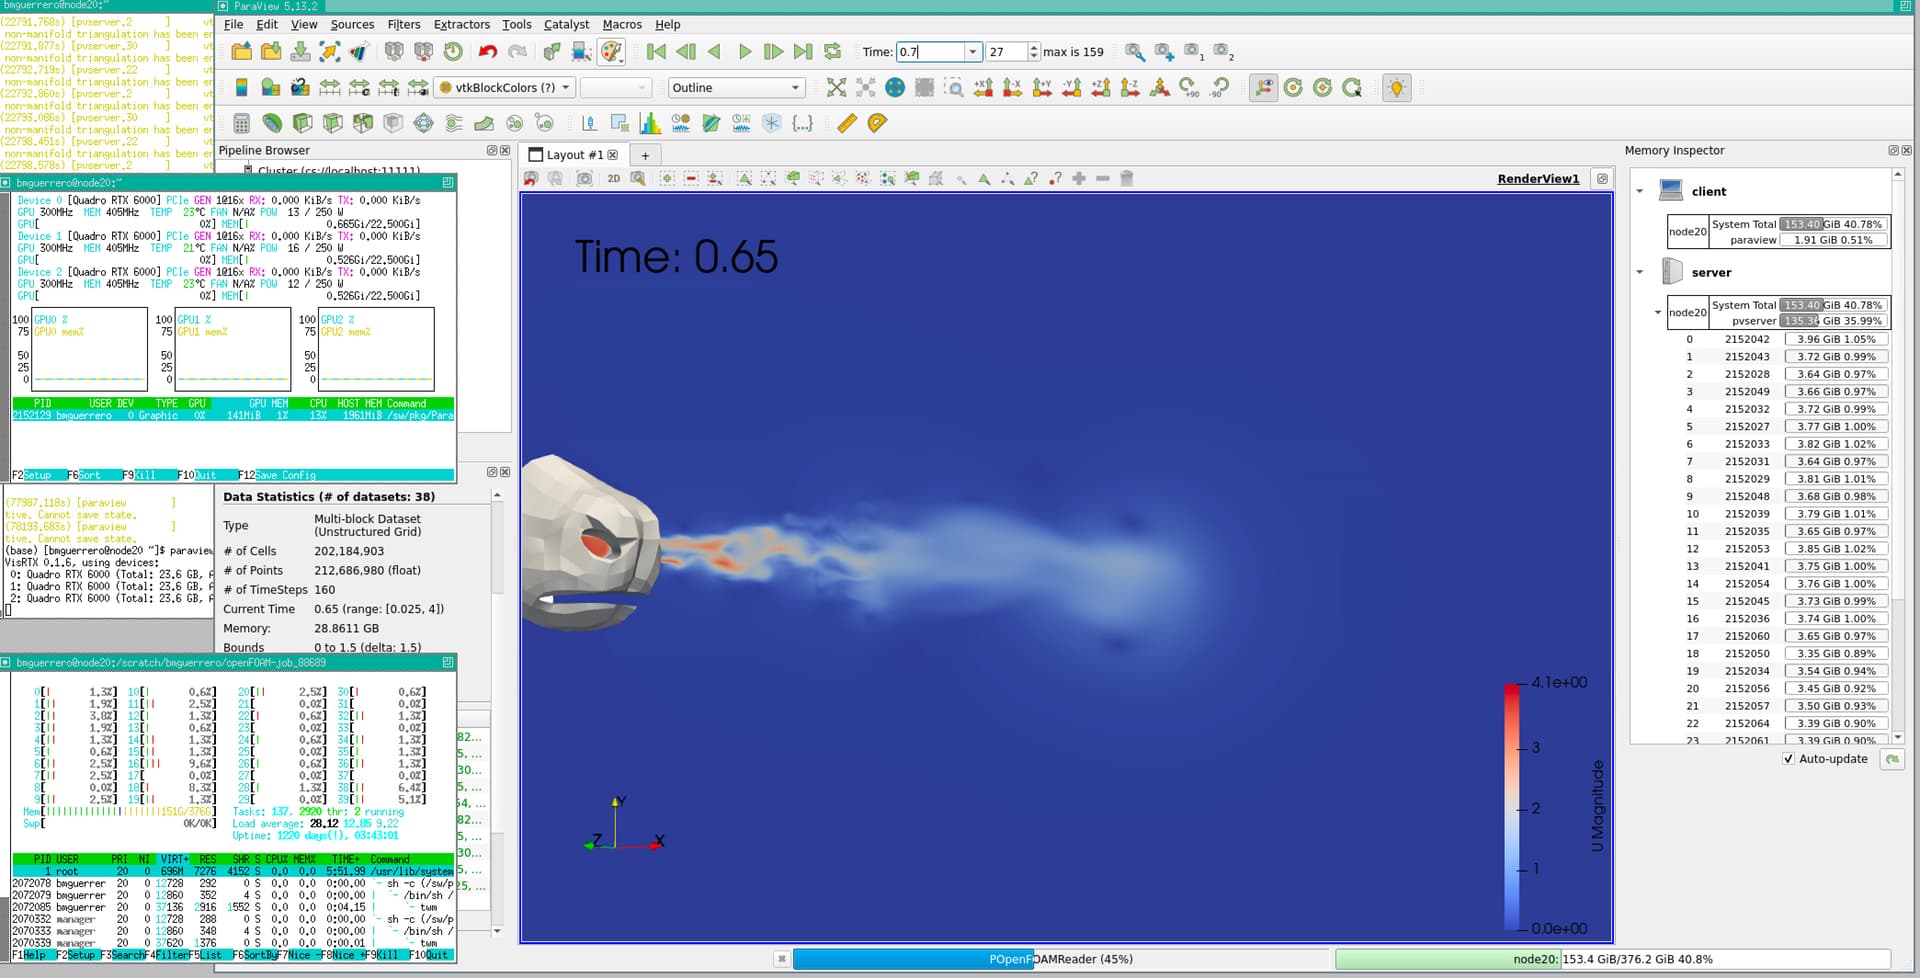
It seems that the cluster was not working correctly with some commands, Now i’m working on a pvserver started on a node with command: mpiexec -np 38 pvserver --mesa --mpi (I added --mpi) and then I connected to it on the same node launching Paraview with paraview --parallel. The load time has decreased substantially (about 5 min) and the node is fully utilized. I add a screenshot when the program is loading a time step.
I think it is a bit difficult to share my data because the folder for each processor is 11gb in size, the total size is about 4 tb. 😅 😅
Another thing I have noticed is that using mpiexec -np 180 pvbatch --mesa --mpi (again adding --mpi) with a Paraview non GUI build has allowed me to use more than one node to render images and graphics and this speeds up the process even more. Now I have been having problems saving states in .py format, after twice exporting in this format paraview does not save new states, it does not even create new files.